3. The question library
Questions, skills and role profiles used to build tests.
On this page:
- AI draft questions in the library
- Finding questions
- Writing a question
- Repository tasks
- Agent tasks: directing a coding agent
- Data science notebooks
- Prompt-engineering questions
- Role profiles
- Skills
- A client’s own codebase: cleaning it up first
- Uploading code: secret scan and AI task ideas
AI draft questions in the library
The SetBenchmark library includes a large bank of questions written by AI, covering C, C++, .NET, Java, WordPress, Flutter, Laravel, React Native, React, frontend, Android, iOS, Sanity, Contentstack, DevOps, project management, QA and account management.
Each has an “AI draft” badge until a Kombee engineer has read it and its answer and approved it. You can read and copy an AI draft at any time, but you can’t put it into a test until it is approved: the question picker in a test shows reviewed questions only, and a test with an unreviewed AI draft can’t be published. Filter by skill in the library to find them.
Tests that already had AI drafts in them before reviews were required keep working. On the test page those questions show “AI draft, not reviewed”, with a note asking you to check them before inviting more candidates, or to duplicate the test and swap them.
Finding questions
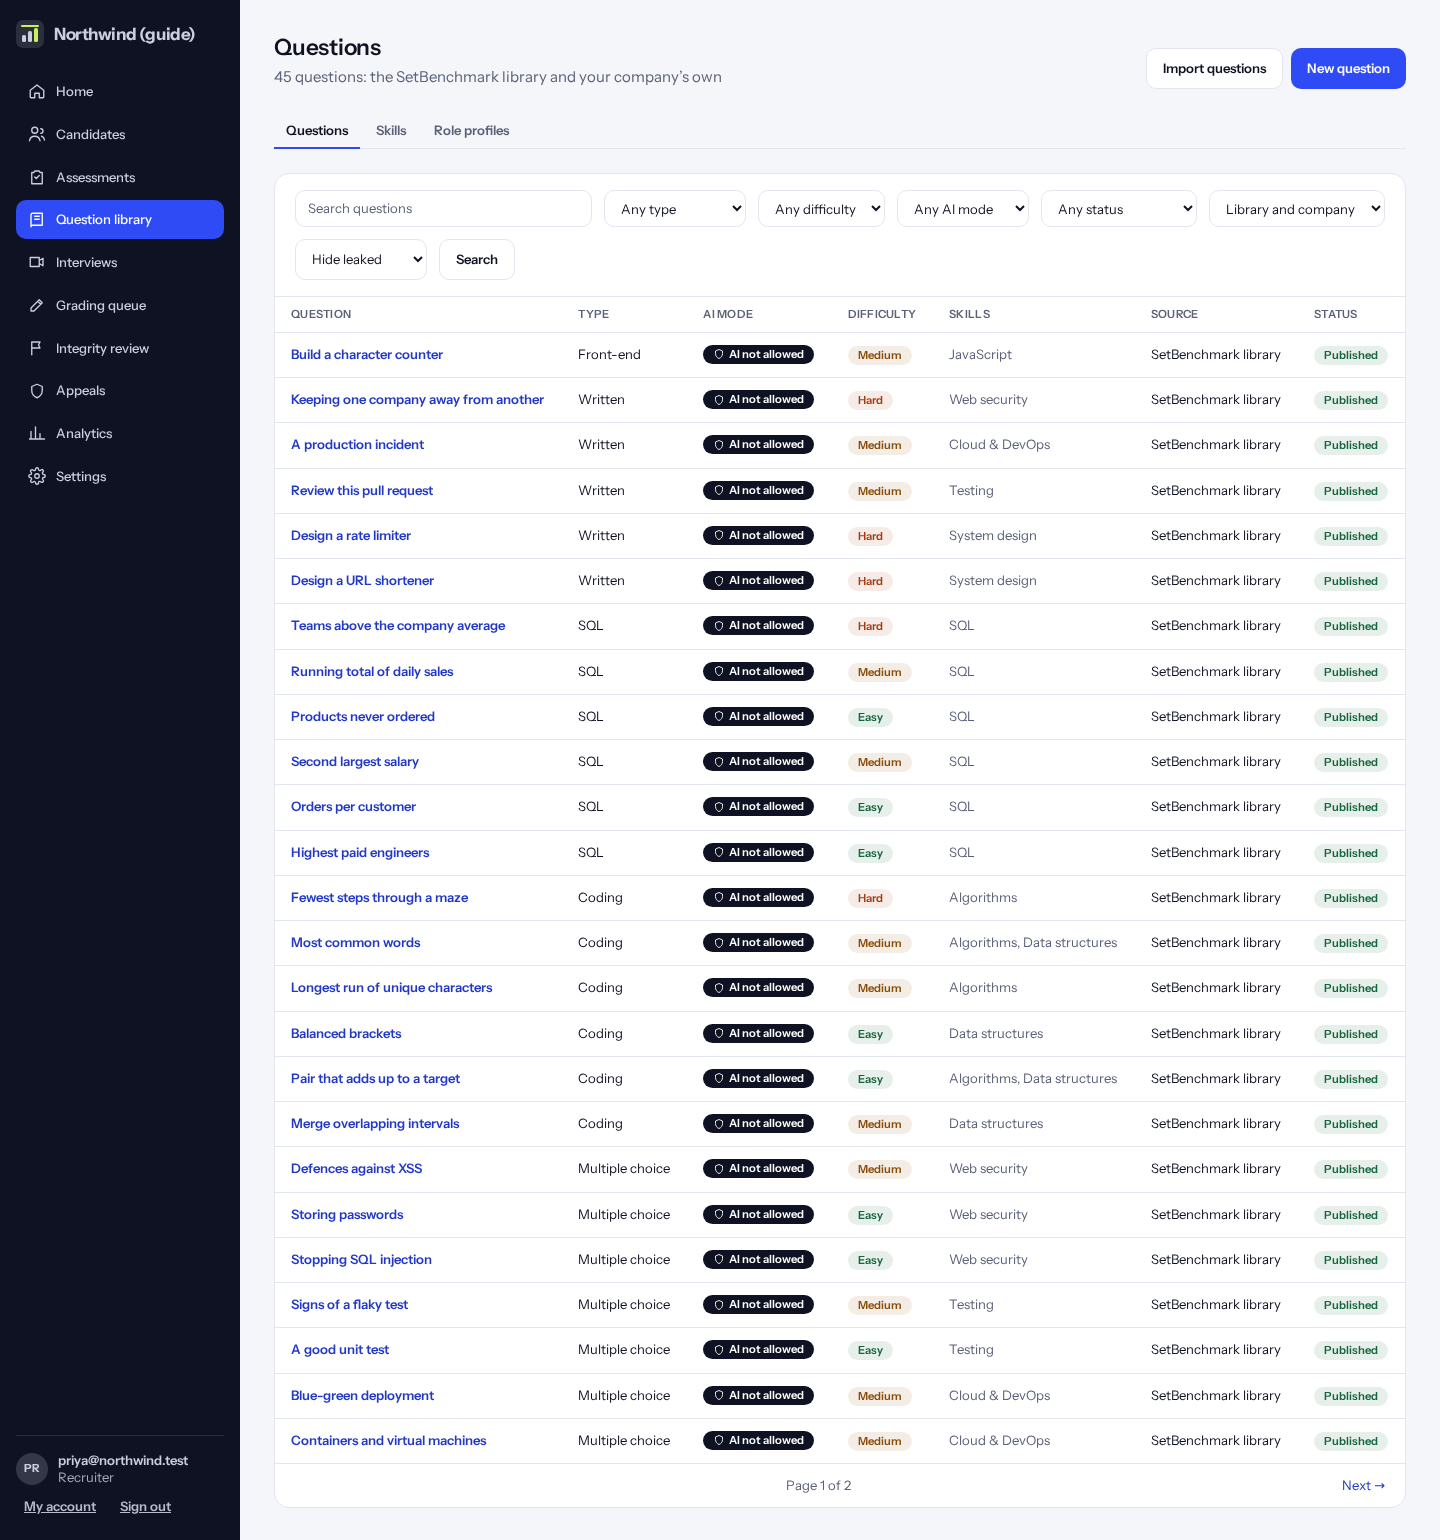
Click “Question library”. You see SetBenchmark’s ready-made questions and your company’s own.
Search by words at the top, and filter on the left by type, AI mode, difficulty, status and source, then click “Search”. Questions reported as leaked online are hidden unless you ask for them.
On a multiple-choice, coding, SQL or fill-in-the-blank question, click “Check if AI can solve it”. An AI answers it, seeing only what a candidate sees, and is marked like a candidate. If it gets full marks the question shows “AI can solve it”, and the library can hide or show only such questions.
Tip: “AI mode” says what a question was written for: answering without AI, with AI allowed, or working with AI.
Writing a question
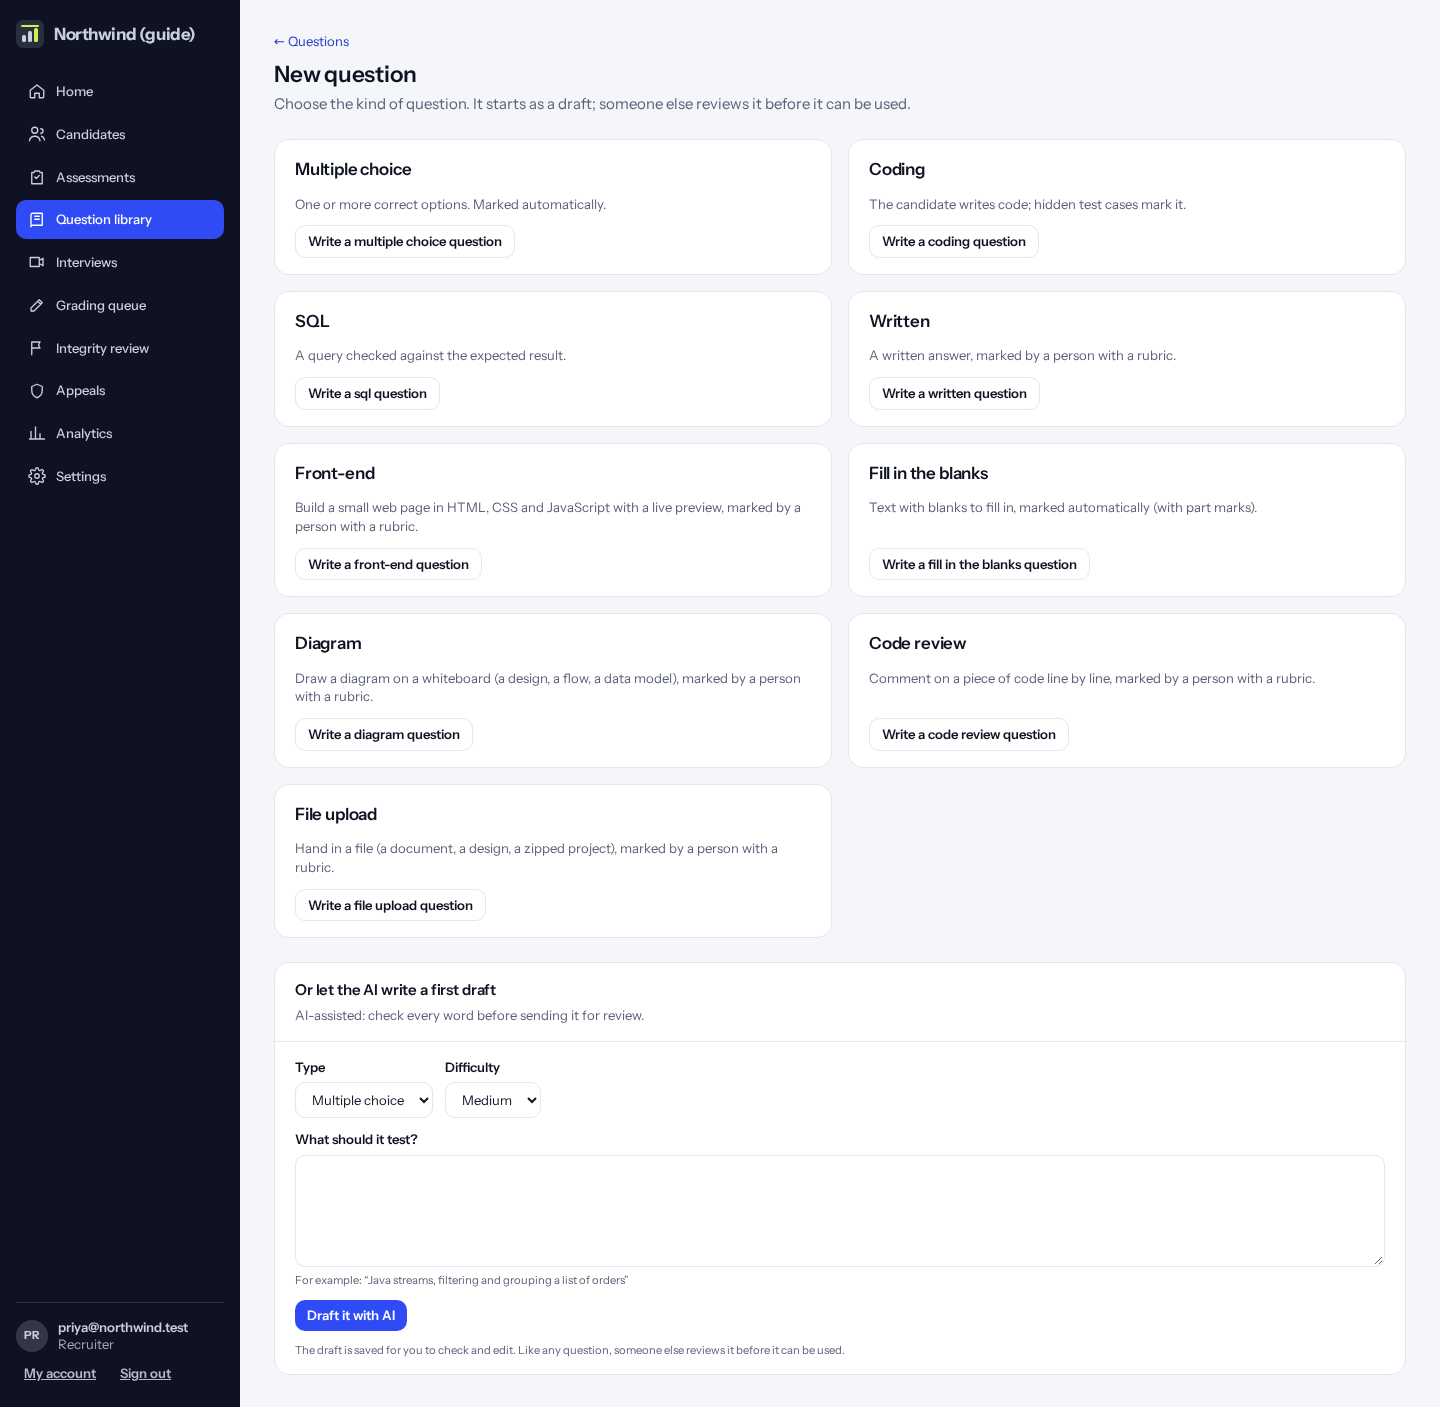
Click “New question” and choose the type: multiple choice, coding, SQL, written answer, a small web page, fill in the blanks, a diagram, a code review, a repository task, a file to upload, a data science notebook, or a prompt-engineering question.
Fill in the title, the question, the difficulty, what it is written for, and the skills it tests. Coding questions also need test cases and a reference answer.
To check a coding question, paste an answer under “Mark this answer” on its page. For each test that fails you see its input, the expected output, what the answer printed and any error, hidden tests included (only authors see these; candidates never do). Each test also says what happened and how long it took: Passed, Wrong output, Didn’t compile (syntax error), Crashed while running, Too slow (time limit), Used too much memory, or Stopped by the sandbox. The same words appear on a candidate’s page, in the candidate’s own example runs and in Practice. Code is written in the same editor candidates use; open “Test against my own input” to run it on any input you type.
How to do it:
- Click “New question” and pick the type.
- Fill in the form and click “Save”.
- Click “Send for review”. A second person must approve it before it can go into a test.
Tip: A reviewer can “Retire” a question so it can’t go into new tests, and “Bring back” a retired one: it is live again with its approved version (or a draft if it was never approved).
Repository tasks
A repository task gives the candidate a small codebase to fix or extend, in JavaScript (also ServiceNow), TypeScript, Python, Go, Java, SAP ABAP, Salesforce, Workday integrations (XSLT) or DevOps and cloud. Choose “Repository task” under “New question”.
1 · Source repository: paste a public GitHub address with a branch or tag and click “Import”, upload a .zip (up to 4 MB; for a private repository, download it as a .zip), or click “Start from the example”. Only text files are kept: dependencies, build output, .git and pictures are left out, and “files left out” lists them. At most 200 files and 1 MB in all. The question keeps its own copy, so later changes to the repository don’t affect it.
Imported code (from GitHub or a .zip) is removed 30 days after the last invitation to any test using it closes: the box “Remove this code 30 days after the last test using it closes” is ticked to start with. The files are replaced by a short note and the question is retired; scores and marks are kept. Code still in a draft test, or never used in a test, stays. If the code is yours to reuse, untick the box. To use a removed task again, import the code again.
2 · What candidates can see and change: give each file a rule. “Can change”: the candidate edits it. “Read only”: shown but locked. “Grading only”: never shown to the candidate, and added back when the answer is marked. When there are grading-only test files, only they decide the score, so tests a candidate writes can’t raise it. Tick “Candidates may add files” to let them add a test of their own.
3 · How it’s scored: the grading tests’ share (60% to start with) is split by how many grading tests pass; the rest is a rubric a reviewer marks. At 100% no rubric is needed and it’s marked automatically. Set how long one test run may take (5 to 60 seconds). For Go, a run currently takes about 40 seconds, so set 60.
4 · Solution: add the changed files that solve the task. It’s never shown to candidates. “Check the grading tests” runs the tests twice: with the solution every grading test should pass, and with the files untouched at least one should fail. The same check runs when you send the question for review.
How to do it:
- Click “New question”, then “Write a repository task question”.
- Import the files or start from the example, and pick the language.
- Set each file’s rule, the tests’ share and the rubric.
- Add the solution and click “Check the grading tests”.
- Save, then send it for review.
Agent tasks: directing a coding agent
In the task editor, tick “Candidates direct a coding agent”. The test must allow AI. The candidate tells the agent what to do, and it proposes a step at a time. Nothing changes until they approve the step, and they can reject it or give a new instruction. The chat assistant is off on these tasks, so every AI step is on the record.
The agent sees only the files the candidate can see, never the grading tests or the solution. It can take 40 steps on a task. It can’t run anything: the candidate runs the tests. If your test sets the assistant to make mistakes on purpose, about one step in four is a tempting shortcut, and the candidate is told this can happen.
To see one working, the SetBenchmark library has a ready agent task: “Fix the refund total with the coding agent” (JavaScript, easy). Put it in a test that allows AI, invite yourself, and try it.
Data science notebooks
A notebook question gives candidates one or more datasets (CSV, JSON or other text files, up to 500 KB each) and Python cells to work in, with pandas, NumPy, SciPy and scikit-learn and no internet. They run their cells and see each cell’s output under it, as in Jupyter.
In the editor: add the datasets (they appear read-only under data/), write the starting cells (start each with a line “# %%”), and write the grading checks as a Python unittest file that imports the notebook as notebook and tests its variables, for example self.assertEqual(notebook.total, 30). Sample checks are optional: candidates can run those. Add the solution cells, then click “Check the grading checks”: every check must pass with the solution and at least one must fail with the starting cells.
Choose how much the checks mark (70% by default); a reviewer marks the rest with the rubric, such as clear, idiomatic pandas. The Task catalogue has a ready-made one, “Data science notebook”.
Prompt-engineering questions
A prompt question asks the candidate to write a prompt for the AI. You add test cases: an input (a customer message, a document, some data) and, in plain words, what a good answer does (for example “Answers with the single word ‘billing’”). Tick “Hidden” on cases candidates shouldn’t see: they count only when the answer is marked.
When it is marked, the prompt runs on every case, with the case’s input where the prompt says {{input}} (or after the prompt), and an AI judge checks each answer against what you expected. The share of cases passed earns the cases’ part of the points (70% by default); a reviewer marks the rest with the rubric, such as a clear, robust prompt. The reviewer sees each case’s answer and verdict.
Each case uses your company’s AI allowance, both when candidates try their prompt and when it is marked. The Task catalogue has a ready-made one, “Prompt engineering”.
Role profiles
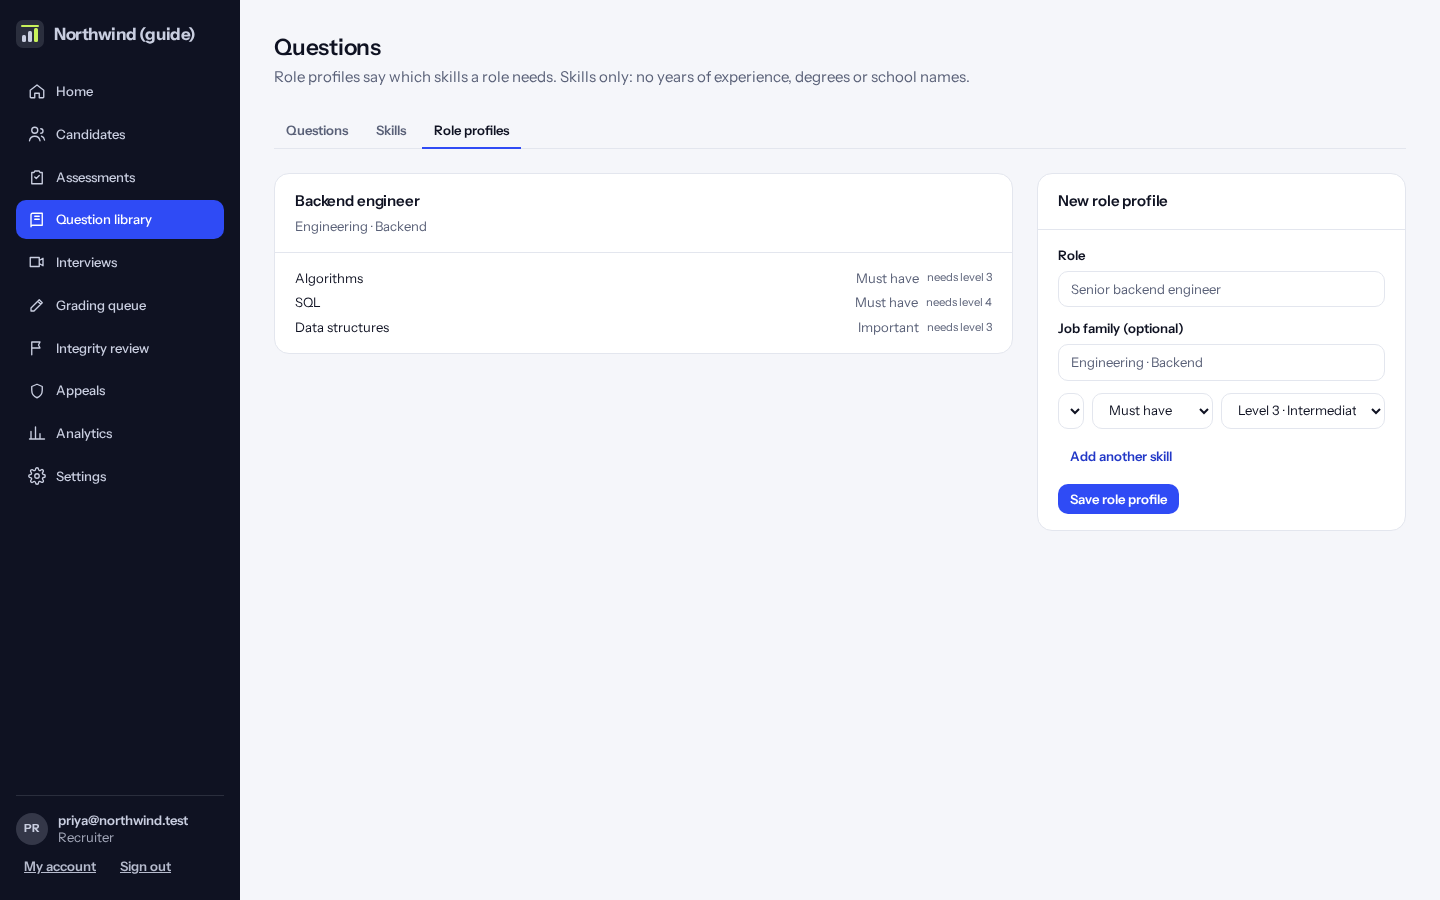
A role profile lists the skills a job needs, how important each is, and the level (1 to 5) needed. Templates, the skill map and “roles that fit” all use these.
If a skill isn’t tested by any published question, the profile warns you.
Skills
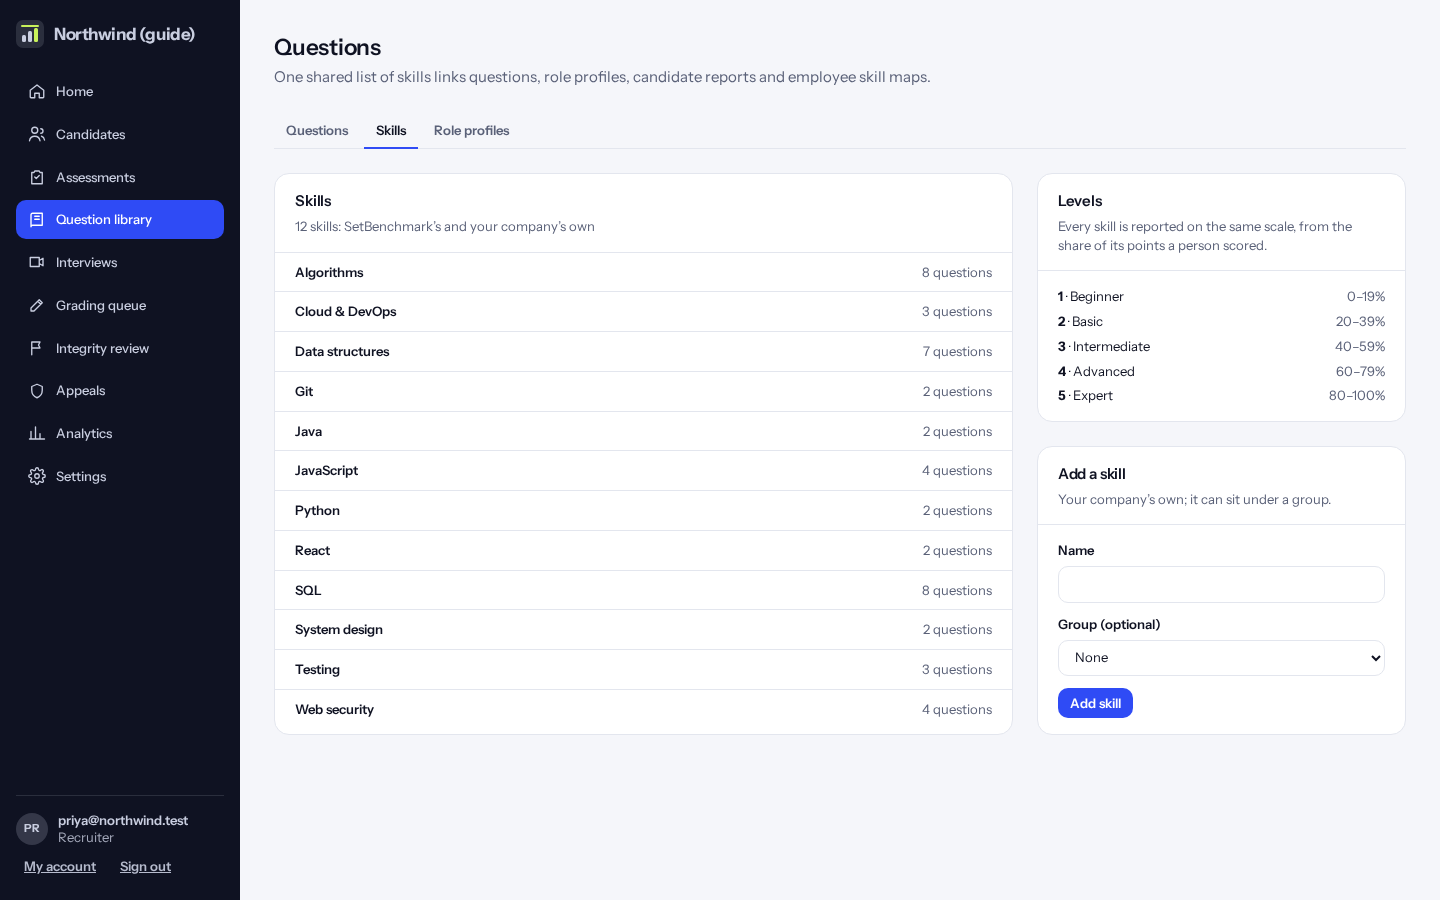
The list of skills, with how many questions test each one. Add your own skills here.
A client’s own codebase: cleaning it up first
To test candidates on the client’s real work, import the client’s code into a repository task (a .zip from their repository), then use “Clean up a client’s code” before anything else. Under “Names to replace”, list the client’s name, products and internal systems with what to put instead, one per line, for example Acme Pay => Shop Co. They’re replaced in the code and in file names, keeping their case and style (AcmePay becomes ShopCo, acme-pay becomes shop-co), so the code still fits together.
Ticked to start with, it also replaces email addresses, internal host names and URLs (public sites such as github.com are kept), IP addresses, phone numbers (+91 and +971, or 10-digit mobiles in quotes), AWS account numbers and copyright lines. “Every change” lists what changed, file by file. Run the tests again afterwards, and keep “Remove this code 30 days after the last test using it closes” ticked.
Then, for senior hires, click “Make an AI pull request review from this code”: AI writes a pull request against the cleaned code with 6 to 8 planted problems, saved as a new draft code review question for you to check. Optionally say what it should change, for example “retries for payments”.
Tip: Secrets (keys, tokens, passwords in code) still stop the import: remove them in the client’s repository first. The clean-up runs on SetBenchmark’s server and nothing is sent to an AI; only the PR review draft uses AI, and your code isn’t used to train models.
Uploading code: secret scan and AI task ideas
When you import a repository for a repository task, we check it for secrets such as AWS keys, private keys, tokens and passwords in code. If any are found the import stops and tells you the file and line. Remove them and import again. Real-looking email addresses are listed for you to check, but don’t stop the import.
Click “Suggest 3 tasks with AI” for a bug fix, a feature and a refactor based on the code, with how to test each. You choose and write the task. Your code isn’t used to train models.